High-density GPU compute
Professional-grade inference GPUs and server-class CPUs in a pre-validated configuration, built for LLM, vision and retrieval workloads.
Plug-and-play liquid-cooled AI nodes with a ready-to-run inference stack. No new data hall. No cloud lock-in. Your models and your data stay on your site.
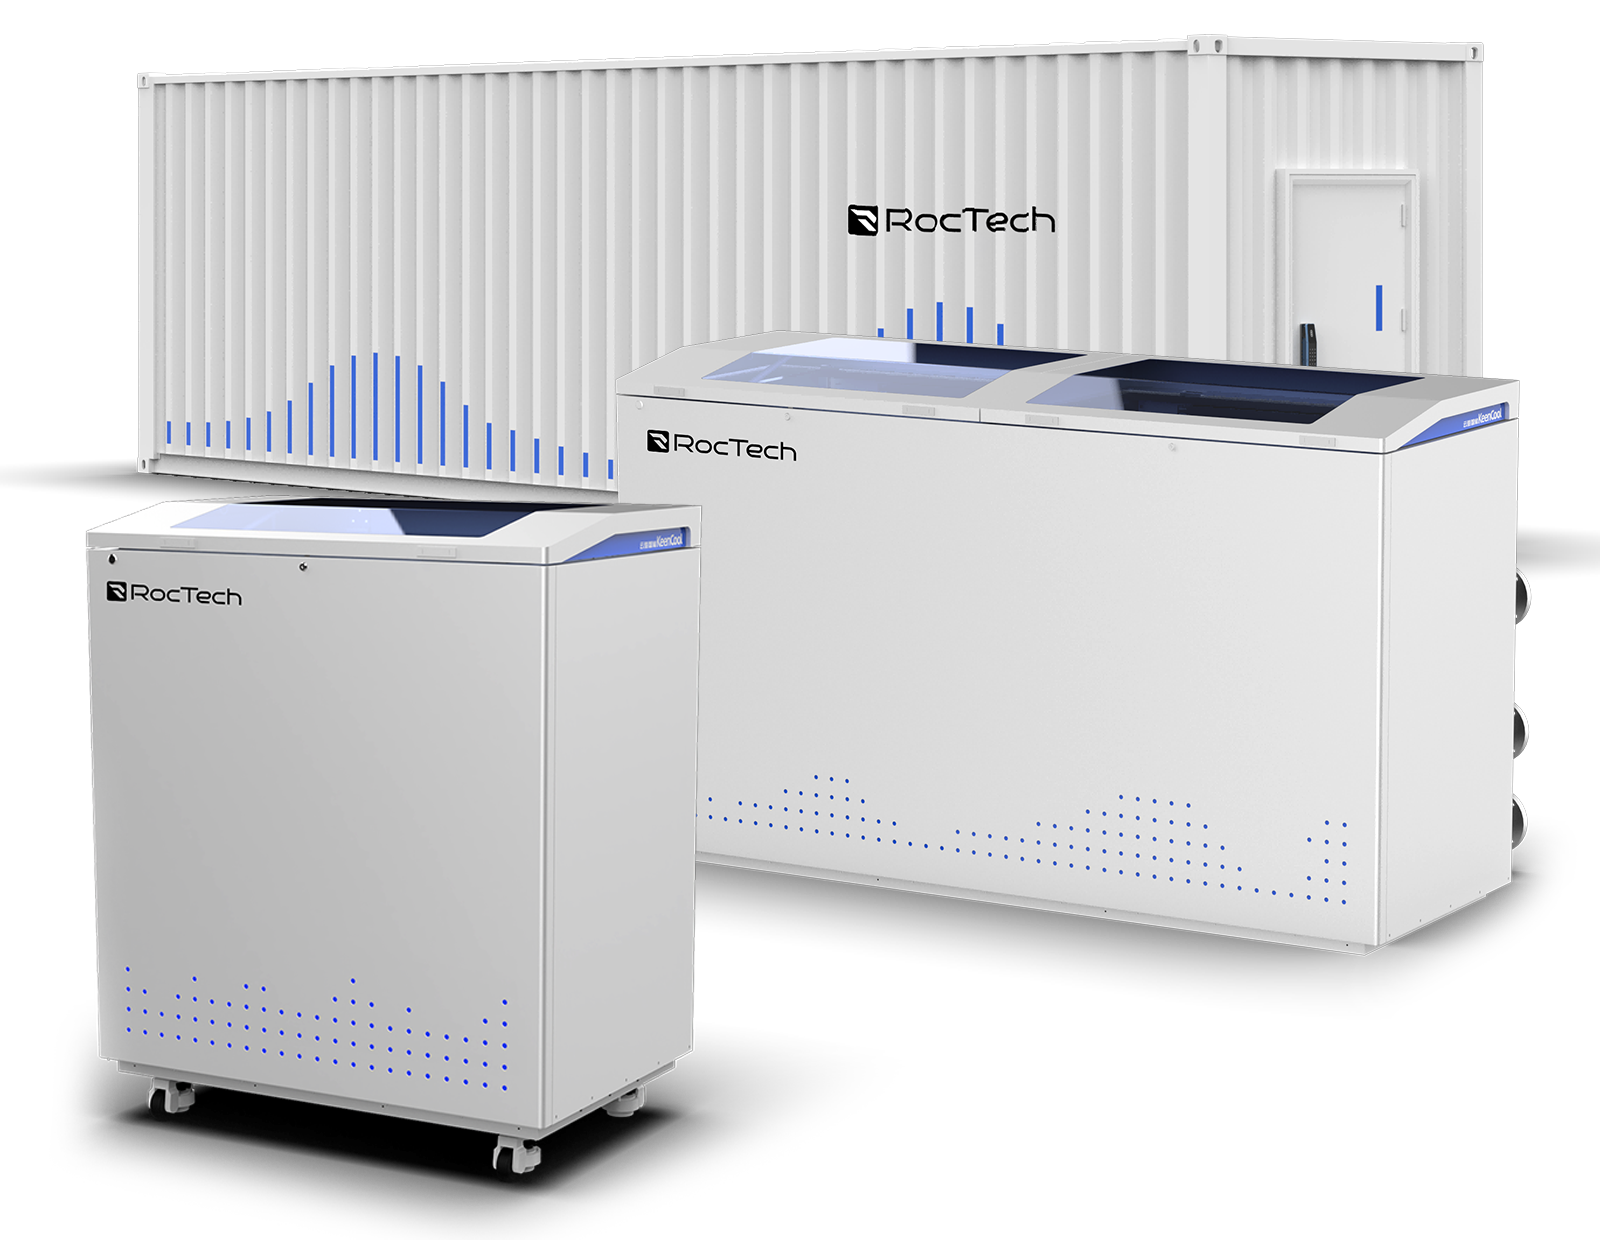
Building AI capacity usually means three suppliers, a new machine room and months of waiting. We integrate compute, thermal management and the inference stack into a single outdoor node you can order, place and switch on.
Professional-grade inference GPUs and server-class CPUs in a pre-validated configuration, built for LLM, vision and retrieval workloads.
Direct-to-chip liquid loops keep GPUs at stable temperatures, run quieter than air-only designs, and open the door to waste-heat reuse.
Container runtime, OpenAI-compatible inference APIs, curated model packs and a fleet console, installed and tested before shipping.
We review your workloads, site, power and network, and recommend the right node configuration.
Nodes are assembled, burn-in tested and loaded with software at our facility.
On-site placement and commissioning. Connect power, network and water-side services.
Remote monitoring, updates and support keep your fleet healthy.
Vision inspection, predictive maintenance and plant-floor assistants with low latency.
Distributed inference at base stations, exchanges and edge colocation sites.
Regulated data stays inside your perimeter while you run modern AI models.
Shared private AI capacity for tenants, research teams and internal tools.
Share your use case and site details. Our engineers will come back with a recommended configuration and a deployment plan.
Get in Touch